VS Code Chat with Inference
VS Code Chat can connect to Serenity* Star's inference models through the OpenAI-compatible Responses endpoint. You can register one or more inference models as custom models and then chat with them from the Chat view while you code.
This page explains how to add an inference model as a custom model inside VS Code Chat. BYOK models work without a GitHub account or a Copilot plan, although some VS Code features, such as inline suggestions and semantic search, still require GitHub Copilot.
Prerequisites
- Visual Studio Code installed. Download VS Code
- VS Code Chat enabled. See AI language models in VS Code for information about using Chat and adding your own language models.
- A Serenity* Star API key (see API Keys). Important: the API key (or user) must be authorized to run AI Services.
- The model identifier of the inference model you want to use, as a
vendor:modelvalue (for exampleanthropic:claude-sonnet-5). See Selecting the model.
How it works
VS Code Chat's custom models live under the customendpoint vendor. Each entry points at the inference Responses URL and lists one or more models, each carrying its own capabilities and limits. VS Code sends a model's id as the model field in the request body, and the generic endpoint uses it to select the model, so every model shares the same url (.../api/v2/inference/responses) and you can list many models, and vendors, under a single entry. The configuration is stored in a chatLanguageModels.json file in your VS Code user profile. The command palette flow below creates the entry and opens that file for you to add your models.
Configuration
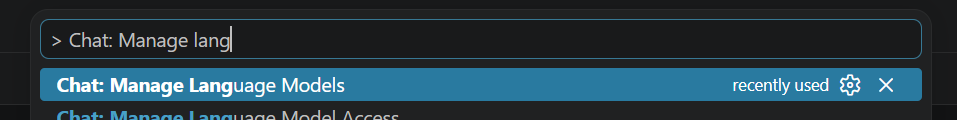
- In VS Code, open the command palette (
Ctrl+Shift+P/Cmd+Shift+P) and runChat: Manage Language Models.
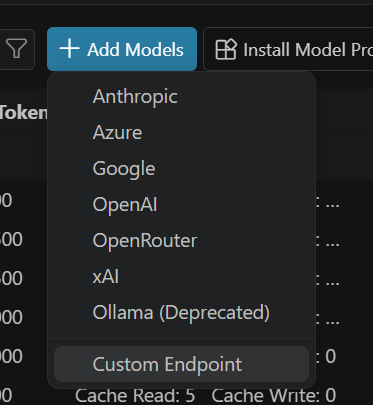
- Click Add Models and choose the Custom Endpoint option.
- When prompted for the group name, enter anything you like, for example
Serenity* Star Inference. - When prompted for the API key, paste your Serenity* Star API key.
- When prompted for the API type, choose Responses.
- VS Code opens
chatLanguageModels.jsonso you can configure the models. Add your inference model using the example below, then save.
[
  {
    "name": "Serenity* Star Inference",
    "vendor": "customendpoint",
    "apiKey": "${input:chat.lm.secret.inference}",
    "apiType": "responses",
    "models": [
      {
        "id": "anthropic:claude-sonnet-5",
        "name": "Claude Sonnet 5 [Anthropic]",
        "url": "https://api.serenitystar.ai/api/v2/inference/responses",
        "toolCalling": true,
        "vision": true,
        "maxInputTokens": 200000,
        "maxOutputTokens": 64000,
        "apiType": "responses",
        "zeroDataRetentionEnabled": true
      },
      {
        "id": "orion/pro-26.2",
        "name": "Orion 26.2 Pro [Serenity Cloud]",
        "url": "https://api.serenitystar.ai/api/v2/inference/responses",
        "toolCalling": true,
        "vision": true,
        "maxInputTokens": 128000,
        "maxOutputTokens": 32000,
        "apiType": "responses",
        "zeroDataRetentionEnabled": true
      }
    ]
  }
]
| Field | Notes |
|---|---|
vendor | Always customendpoint for an OpenAI-compatible endpoint. |
apiKey | Your Serenity API key. The ${input:...} form prompts for the value and stores it in VS Code's secret storage instead of in plain text. |
id | The model identifier, as a vendor:model value (for example anthropic:claude-sonnet-5). VS Code sends it as the model field in the request body, and the endpoint uses it to select the model. |
name | A friendly display name shown in the model picker. |
url | The generic inference Responses endpoint: https://api.serenitystar.ai/api/v2/inference/responses. The same URL is used for every model; the id selects which one. |
apiType | responses, matching the endpoint in url. |
toolCalling, vision | Set true if the selected model supports function calling and image input. |
maxInputTokens, maxOutputTokens | Context and output limits for the selected model; adjust to the model you target. |
zeroDataRetentionEnabled | Required when using the Responses API. |
zeroDataRetentionEnabled: true for the Responses APIInference does not persist conversation state server-side. With the Responses API, clients can otherwise reference a stored prior turn by its response ID, which the inference endpoint has no record of. Setting zeroDataRetentionEnabled: true tells VS Code to send the full conversation on every request rather than relying on server-side retention, so multi-turn chats work correctly.
Select the model
Once you save chatLanguageModels.json, open the Chat view, open the model picker above the chat input, and select your inference model. Reload VS Code if it does not appear immediately.
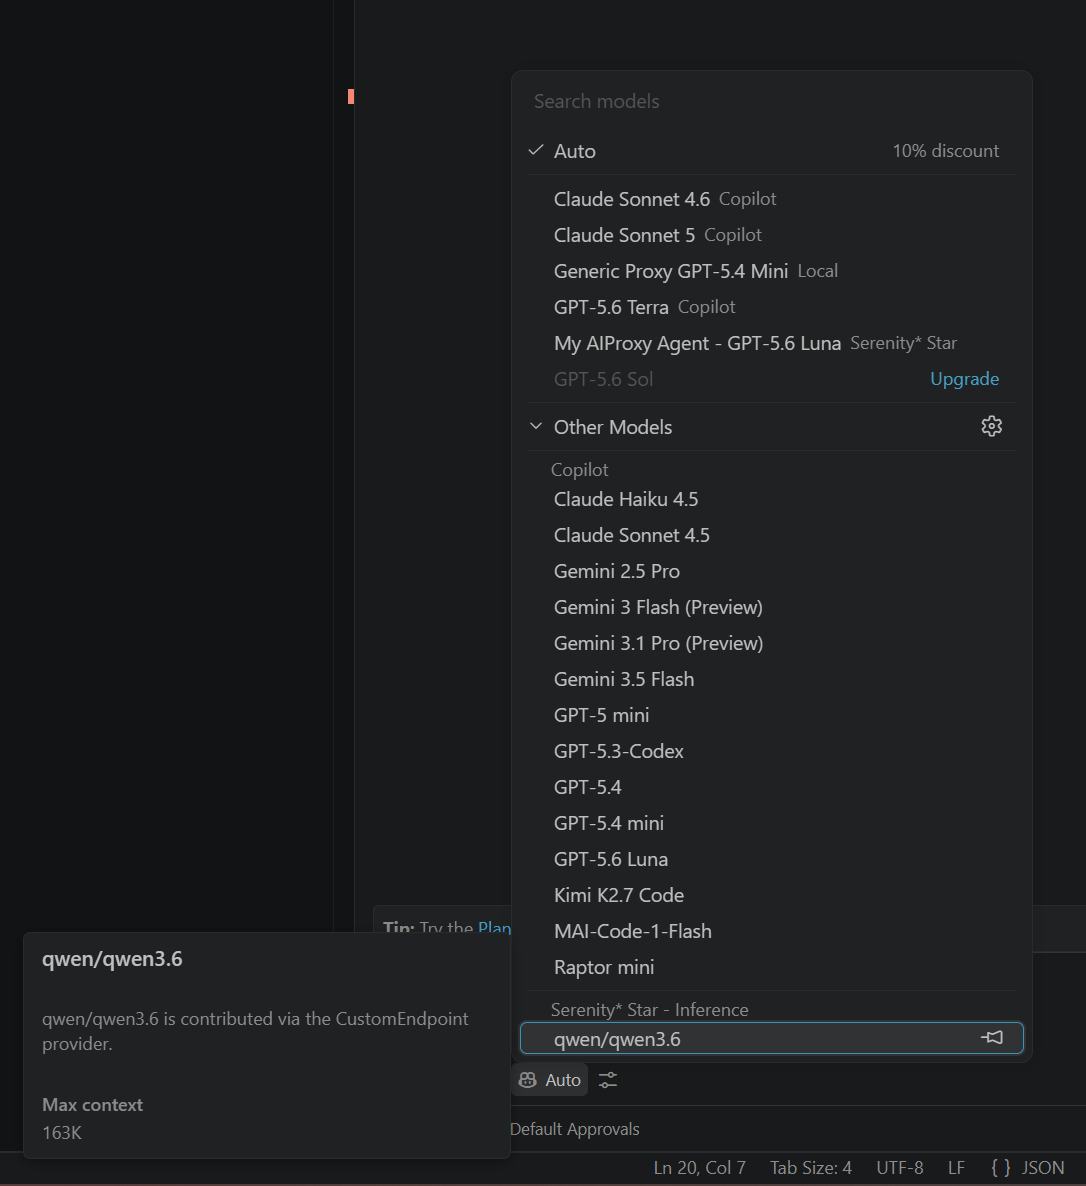
You can then type into the Chat input as usual. Your prompts will be answered directly by the selected inference model.